Hardening the Robot Brain
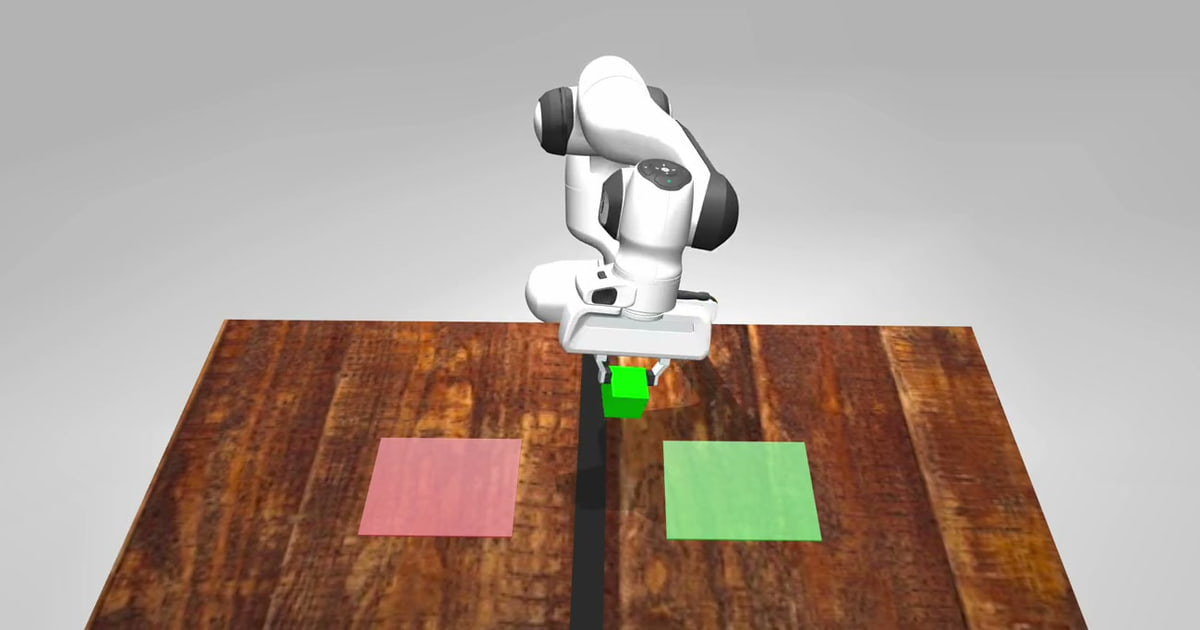
Continuing to improve the Mamba + LNN powered Franka Emika robot arm with parallelized cloud training, improved models, and closing the sim-to-real gap.
Robotics Control & Simulation Engineering
I'm a Software Engineer and Roboticist. I write control code, build physics simulations, and the cloud infrastructure that runs them. Take a look at my write-ups to see what I've been working on.
Demonstrations & Simulations
θ1: -180.0°
θ2: -180.0°
x: 0.00 m
u: 0.0 N
SWING_UP · iLQR + TVLQR
One actuator against three degrees of freedom. The swing-up follows a trajectory solved offline with iLQR, tracked by a time-varying LQR; an infinite-horizon LQR catches it at the top. Swipe the cursor through a link, or knock it down, and watch it recover.
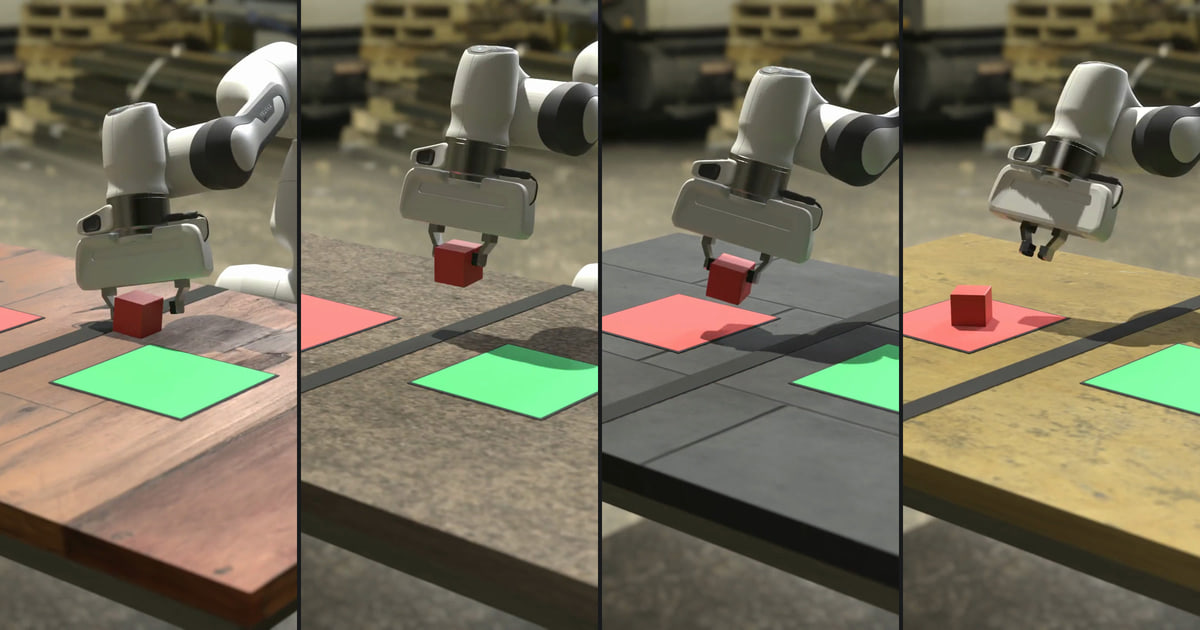
Hardened policy rollout imported from MuJoCo and rendered in Blender: smooth, contact-aware grasping and placement under realistic actuator lag and lighting.
* Note: Trajectories are 100% driven by the trained neural network policy exported from MuJoCo, rendered with photorealistic materials and lighting in Blender.
Industrial robots fail if objects shift by even centimeters. This closed-loop neural policy continuously observes multi-camera pixels and joint telemetry to adapt dynamically in real time.
Physics simulation and applied machine learning to train and validate robotic control before it ever touches hardware.
Cloud pipelines for getting data off the robot and back down again: telemetry ingestion, teleop interfaces, and fleet infrastructure that holds up under real traffic.
Operator dashboards, fleet monitoring UIs, and the on-robot to cloud plumbing that connects them, plus LLM/RAG integration where it actually earns its place.
Continuing to improve the Mamba + LNN powered Franka Emika robot arm with parallelized cloud training, improved models, and closing the sim-to-real gap.
A systems view of continuous robot reinforcement learning: why control splits across a 20 Hz policy loop and a 500 Hz PD loop, how GAE trades bias for variance, the truncation bug that quietly biases every late-episode advantage, what the PPO clip does and does not constrain, and which metrics to read when a run goes bad.
Designing a multi-rate vision-based pick-and-place policy for a 7-DOF Franka Panda arm from first principles: 10 Hz Mamba-3 SSM Cortex, 50 Hz Liquid CfC Brainstem, SpatialSoftmax, and DLS Inverse Kinematics.

My journey in robotics started from the lowest level up—making LEDs blink using assembly code on microcontrollers. I was one of the first 30 students to graduate from Texas A&M with a degree in Mechatronics.
After four years engineering distributed backend systems at Amazon AWS, I came back to my robotics roots. Most of my time now goes to control theory and physics simulation in MuJoCo. Lately I've been tinkering with reinforcement learning and small robotics-friendly models like Mamba 3 and Liquid Neural Nets.
Read My Full StoryI can help with different pieces of a robotics pipeline: control code, simulation, the training loop, or the infrastructure underneath it. Tell me what you're working on and where you're stuck.